
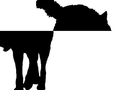
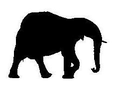
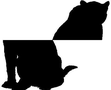
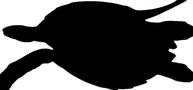
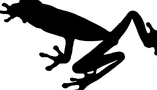
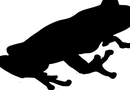
Sample stimuli




How to use
from brainscore_vision import load_benchmark
benchmark = load_benchmark("Baker2022frankenstein-accuracy_delta")
score = benchmark(my_model)
Model scores
Min Alignment
Max Alignment
|
Rank |
Model |
Score |
|---|---|---|
| 1 |
.983
|
|
| 2 |
.974
|
|
| 3 |
.972
|
|
| 4 |
.957
|
|
| 5 |
.940
|
|
| 6 |
.939
|
|
| 7 |
.929
|
|
| 8 |
.929
|
|
| 9 |
.929
|
|
| 10 |
.899
|
|
| 11 |
.897
|
|
| 12 |
.889
|
|
| 13 |
.887
|
|
| 14 |
.874
|
|
| 15 |
.873
|
|
| 16 |
.867
|
|
| 17 |
.867
|
|
| 18 |
.865
|
|
| 19 |
.862
|
|
| 20 |
.858
|
|
| 21 |
.855
|
|
| 22 |
.854
|
|
| 23 |
.850
|
|
| 24 |
.844
|
|
| 25 |
.841
|
|
| 26 |
.824
|
|
| 27 |
.810
|
|
| 28 |
.806
|
|
| 29 |
.803
|
|
| 30 |
.801
|
|
| 31 |
.799
|
|
| 32 |
.798
|
|
| 33 |
.793
|
|
| 34 |
.775
|
|
| 35 |
.770
|
|
| 36 |
.767
|
|
| 37 |
.767
|
|
| 38 |
.766
|
|
| 39 |
.766
|
|
| 40 |
.762
|
|
| 41 |
.761
|
|
| 42 |
.756
|
|
| 43 |
.754
|
|
| 44 |
.752
|
|
| 45 |
.741
|
|
| 46 |
.741
|
|
| 47 |
.731
|
|
| 48 |
.731
|
|
| 49 |
.730
|
|
| 50 |
.727
|
|
| 51 |
.726
|
|
| 52 |
.724
|
|
| 53 |
.724
|
|
| 54 |
.717
|
|
| 55 |
.715
|
|
| 56 |
.714
|
|
| 57 |
.713
|
|
| 58 |
.712
|
|
| 59 |
.698
|
|
| 60 |
.696
|
|
| 61 |
.692
|
|
| 62 |
.681
|
|
| 63 |
.680
|
|
| 64 |
.679
|
|
| 65 |
.671
|
|
| 66 |
.671
|
|
| 67 |
.666
|
|
| 68 |
.666
|
|
| 69 |
.662
|
|
| 70 |
.658
|
|
| 71 |
.658
|
|
| 72 |
.647
|
|
| 73 |
.645
|
|
| 74 |
.644
|
|
| 75 |
.641
|
|
| 76 |
.627
|
|
| 77 |
.623
|
|
| 78 |
.617
|
|
| 79 |
.608
|
|
| 80 |
.607
|
|
| 81 |
.599
|
|
| 82 |
.578
|
|
| 83 |
.576
|
|
| 84 |
.572
|
|
| 85 |
.569
|
|
| 86 |
.568
|
|
| 87 |
.568
|
|
| 88 |
.567
|
|
| 89 |
.558
|
|
| 90 |
.552
|
|
| 91 |
.545
|
|
| 92 |
.539
|
|
| 93 |
.536
|
|
| 94 |
.527
|
|
| 95 |
.523
|
|
| 96 |
.519
|
|
| 97 |
.503
|
|
| 98 |
.503
|
|
| 99 |
.496
|
|
| 100 |
.494
|
|
| 101 |
.487
|
|
| 102 |
.485
|
|
| 103 |
.485
|
|
| 104 |
.465
|
|
| 105 |
.464
|
|
| 106 |
.463
|
|
| 107 |
.463
|
|
| 108 |
.462
|
|
| 109 |
.457
|
|
| 110 |
.454
|
|
| 111 |
.453
|
|
| 112 |
.448
|
|
| 113 |
.448
|
|
| 114 |
.448
|
|
| 115 |
.446
|
|
| 116 |
.435
|
|
| 117 |
.429
|
|
| 118 |
.427
|
|
| 119 |
.420
|
|
| 120 |
.418
|
|
| 121 |
.412
|
|
| 122 |
.410
|
|
| 123 |
.404
|
|
| 124 |
.398
|
|
| 125 |
.395
|
|
| 126 |
.392
|
|
| 127 |
.378
|
|
| 128 |
.374
|
|
| 129 |
.372
|
|
| 130 |
.365
|
|
| 131 |
.365
|
|
| 132 |
.362
|
|
| 133 |
.351
|
|
| 134 |
.343
|
|
| 135 |
.339
|
|
| 136 |
.335
|
|
| 137 |
.335
|
|
| 138 |
.335
|
|
| 139 |
.334
|
|
| 140 |
.324
|
|
| 141 |
.314
|
|
| 142 |
.313
|
|
| 143 |
.310
|
|
| 144 |
.308
|
|
| 145 |
.305
|
|
| 146 |
.301
|
|
| 147 |
.288
|
|
| 148 |
.286
|
|
| 149 |
.284
|
|
| 150 |
.282
|
|
| 151 |
.278
|
|
| 152 |
.276
|
|
| 153 |
.276
|
|
| 154 |
.270
|
|
| 155 |
.270
|
|
| 156 |
.257
|
|
| 157 |
.255
|
|
| 158 |
.232
|
|
| 159 |
.232
|
|
| 160 |
.223
|
|
| 161 |
.220
|
|
| 162 |
.220
|
|
| 163 |
.212
|
|
| 164 |
.204
|
|
| 165 |
.201
|
|
| 166 |
.192
|
|
| 167 |
.171
|
|
| 168 |
.160
|
|
| 169 |
.158
|
|
| 170 |
.156
|
|
| 171 |
.156
|
|
| 172 |
.155
|
|
| 173 |
.144
|
|
| 174 |
.142
|
|
| 175 |
.135
|
|
| 176 |
.134
|
|
| 177 |
.131
|
|
| 178 |
.119
|
|
| 179 |
.116
|
|
| 180 |
.111
|
|
| 181 |
.098
|
|
| 182 |
.096
|
|
| 183 |
.089
|
|
| 184 |
.088
|
|
| 185 |
.068
|
|
| 186 |
.055
|
|
| 187 |
.042
|
|
| 188 |
.038
|
|
| 189 |
.028
|
|
| 190 |
.028
|
|
| 191 |
.007
|
|
| 192 |
.006
|
|
| 193 |
.003
|
|
| 194 |
.002
|
|
| 195 |
.000
|
|
| 196 |
.000
|
|
| 197 |
.000
|
|
| 198 |
.000
|
|
| 199 |
.000
|
|
| 200 |
.000
|
|
| 201 |
.000
|
|
| 202 |
.000
|
|
| 203 |
.000
|
|
| 204 |
.000
|
|
| 205 |
.000
|
|
| 206 |
.000
|
|
| 207 |
.000
|
|
| 208 |
.000
|
|
| 209 |
.000
|
|
| 210 |
.000
|
|
| 211 |
.000
|
|
| 212 |
.000
|
|
| 213 |
.000
|
|
| 214 |
.000
|
|
| 215 |
.000
|
|
| 216 |
.000
|
|
| 217 |
.000
|
|
| 218 |
.000
|
|
| 219 |
.000
|
|
| 220 |
.000
|
|
| 221 |
.000
|
|
| 222 |
.000
|
|
| 223 |
.000
|
|
| 224 |
.000
|
|
| 225 |
.000
|
|
| 226 |
.000
|
|
| 227 |
.000
|
|
| 228 |
.000
|
|
| 229 |
|
|
| 230 |
|
|
| 231 |
|
|
| 232 |
|
|
| 233 |
|
|
| 234 |
|
|
| 235 |
|
|
| 236 |
|
|
| 237 |
|
|
| 238 |
|
|
| 239 |
|
|
| 240 |
|
|
| 241 |
|
|
| 242 |
|
|
| 243 |
|
|
| 244 |
|
|
| 245 |
|
|
| 246 |
|
|
| 247 |
|
|
| 248 |
|
|
| 249 |
|
|
| 250 |
|
|
| 251 |
|
|
| 252 |
|
|
| 253 |
|
|
| 254 |
|
|
| 255 |
|
|
| 256 |
|
|
| 257 |
|
|
| 258 |
|
|
| 259 |
|
|
| 260 |
|
|
| 261 |
|
|
| 262 |
|
|
| 263 |
|
|
| 264 |
|
|
| 265 |
|
|
| 266 |
|
|
| 267 |
|
|
| 268 |
|
|
| 269 |
|
|
| 270 |
|
|
| 271 |
|
|
| 272 |
|
|
| 273 |
|
|
| 274 |
|
|
| 275 |
|
|
| 276 |
|
|
| 277 |
|
|
| 278 |
|
|
| 279 |
|
|
| 280 |
|
|
| 281 |
|
|
| 282 |
|
|
| 283 |
|
|
| 284 |
|
|
| 285 |
|
|
| 286 |
|
|
| 287 |
|
|
| 288 |
|
|
| 289 |
|
|
| 290 |
|
|
| 291 |
|
|
| 292 |
|
|
| 293 |
|
|
| 294 |
|
|
| 295 |
|
|
| 296 |
|
|
| 297 |
|
|
| 298 |
|
|
| 299 |
|
|
| 300 |
|
|
| 301 |
|
|
| 302 |
|
|
| 303 |
|
|
| 304 |
|
|
| 305 |
|
|
| 306 |
|
|
| 307 |
|
|
| 308 |
|
|
| 309 |
|
|
| 310 |
|
|
| 311 |
|
|
| 312 |
|
|
| 313 |
|
|
| 314 |
|
|
| 315 |
|
|
| 316 |
|
|
| 317 |
|
|
| 318 |
|
|
| 319 |
|
|
| 320 |
|
|
| 321 |
|
|
| 322 |
|
|
| 323 |
|
|
| 324 |
|
|
| 325 |
|
|
| 326 |
|
|
| 327 |
|
|
| 328 |
|
|
| 329 |
|
|
| 330 |
|
|
| 331 |
|
|
| 332 |
|
|
| 333 |
|
Benchmark bibtex
@article{BAKER2022104913,
                title = {Deep learning models fail to capture the configural nature of human shape perception},
                journal = {iScience},
                volume = {25},
                number = {9},
                pages = {104913},
                year = {2022},
                issn = {2589-0042},
                doi = {https://doi.org/10.1016/j.isci.2022.104913},
                url = {https://www.sciencedirect.com/science/article/pii/S2589004222011853},
                author = {Nicholas Baker and James H. Elder},
                keywords = {Biological sciences, Neuroscience, Sensory neuroscience},
                abstract = {Summary
                A hallmark of human object perception is sensitivity to the holistic configuration of the local shape features of an object. Deep convolutional neural networks (DCNNs) are currently the dominant models for object recognition processing in the visual cortex, but do they capture this configural sensitivity? To answer this question, we employed a dataset of animal silhouettes and created a variant of this dataset that disrupts the configuration of each object while preserving local features. While human performance was impacted by this manipulation, DCNN performance was not, indicating insensitivity to object configuration. Modifications to training and architecture to make networks more brain-like did not lead to configural processing, and none of the networks were able to accurately predict trial-by-trial human object judgements. We speculate that to match human configural sensitivity, networks must be trained to solve a broader range of object tasks beyond category recognition.}
        }
Ceiling
0.85.Note that scores are relative to this ceiling.
Data: Baker2022frankenstein
Metric: accuracy_delta