
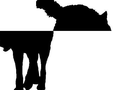
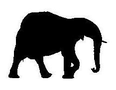
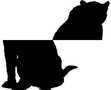
Sample stimuli




How to use
from brainscore_vision import load_benchmark
benchmark = load_benchmark("Baker2022fragmented-accuracy_delta")
score = benchmark(my_model)
Model scores
Min Alignment
Max Alignment
|
Rank |
Model |
Score |
|---|---|---|
| 1 |
.987
|
|
| 2 |
.987
|
|
| 3 |
.987
|
|
| 4 |
.986
|
|
| 5 |
.986
|
|
| 6 |
.985
|
|
| 7 |
.984
|
|
| 8 |
.984
|
|
| 9 |
.984
|
|
| 10 |
.983
|
|
| 11 |
.982
|
|
| 12 |
.982
|
|
| 13 |
.982
|
|
| 14 |
.981
|
|
| 15 |
.978
|
|
| 16 |
.975
|
|
| 17 |
.970
|
|
| 18 |
.965
|
|
| 19 |
.964
|
|
| 20 |
.960
|
|
| 21 |
.960
|
|
| 22 |
.960
|
|
| 23 |
.957
|
|
| 24 |
.954
|
|
| 25 |
.946
|
|
| 26 |
.945
|
|
| 27 |
.944
|
|
| 28 |
.944
|
|
| 29 |
.937
|
|
| 30 |
.935
|
|
| 31 |
.926
|
|
| 32 |
.925
|
|
| 33 |
.917
|
|
| 34 |
.909
|
|
| 35 |
.903
|
|
| 36 |
.901
|
|
| 37 |
.901
|
|
| 38 |
.901
|
|
| 39 |
.889
|
|
| 40 |
.882
|
|
| 41 |
.881
|
|
| 42 |
.868
|
|
| 43 |
.860
|
|
| 44 |
.858
|
|
| 45 |
.858
|
|
| 46 |
.838
|
|
| 47 |
.836
|
|
| 48 |
.836
|
|
| 49 |
.834
|
|
| 50 |
.832
|
|
| 51 |
.832
|
|
| 52 |
.822
|
|
| 53 |
.811
|
|
| 54 |
.806
|
|
| 55 |
.803
|
|
| 56 |
.802
|
|
| 57 |
.799
|
|
| 58 |
.796
|
|
| 59 |
.791
|
|
| 60 |
.788
|
|
| 61 |
.787
|
|
| 62 |
.785
|
|
| 63 |
.774
|
|
| 64 |
.760
|
|
| 65 |
.758
|
|
| 66 |
.756
|
|
| 67 |
.755
|
|
| 68 |
.751
|
|
| 69 |
.740
|
|
| 70 |
.739
|
|
| 71 |
.735
|
|
| 72 |
.734
|
|
| 73 |
.734
|
|
| 74 |
.730
|
|
| 75 |
.723
|
|
| 76 |
.721
|
|
| 77 |
.720
|
|
| 78 |
.709
|
|
| 79 |
.700
|
|
| 80 |
.698
|
|
| 81 |
.691
|
|
| 82 |
.684
|
|
| 83 |
.671
|
|
| 84 |
.670
|
|
| 85 |
.663
|
|
| 86 |
.659
|
|
| 87 |
.656
|
|
| 88 |
.649
|
|
| 89 |
.646
|
|
| 90 |
.626
|
|
| 91 |
.617
|
|
| 92 |
.603
|
|
| 93 |
.602
|
|
| 94 |
.597
|
|
| 95 |
.592
|
|
| 96 |
.590
|
|
| 97 |
.583
|
|
| 98 |
.582
|
|
| 99 |
.575
|
|
| 100 |
.574
|
|
| 101 |
.566
|
|
| 102 |
.558
|
|
| 103 |
.558
|
|
| 104 |
.551
|
|
| 105 |
.550
|
|
| 106 |
.543
|
|
| 107 |
.541
|
|
| 108 |
.538
|
|
| 109 |
.532
|
|
| 110 |
.528
|
|
| 111 |
.524
|
|
| 112 |
.523
|
|
| 113 |
.515
|
|
| 114 |
.507
|
|
| 115 |
.499
|
|
| 116 |
.494
|
|
| 117 |
.488
|
|
| 118 |
.478
|
|
| 119 |
.473
|
|
| 120 |
.470
|
|
| 121 |
.446
|
|
| 122 |
.445
|
|
| 123 |
.438
|
|
| 124 |
.433
|
|
| 125 |
.424
|
|
| 126 |
.421
|
|
| 127 |
.417
|
|
| 128 |
.412
|
|
| 129 |
.412
|
|
| 130 |
.412
|
|
| 131 |
.411
|
|
| 132 |
.400
|
|
| 133 |
.392
|
|
| 134 |
.392
|
|
| 135 |
.388
|
|
| 136 |
.365
|
|
| 137 |
.350
|
|
| 138 |
.336
|
|
| 139 |
.336
|
|
| 140 |
.333
|
|
| 141 |
.323
|
|
| 142 |
.315
|
|
| 143 |
.308
|
|
| 144 |
.308
|
|
| 145 |
.304
|
|
| 146 |
.289
|
|
| 147 |
.287
|
|
| 148 |
.282
|
|
| 149 |
.280
|
|
| 150 |
.274
|
|
| 151 |
.272
|
|
| 152 |
.268
|
|
| 153 |
.264
|
|
| 154 |
.251
|
|
| 155 |
.236
|
|
| 156 |
.221
|
|
| 157 |
.217
|
|
| 158 |
.216
|
|
| 159 |
.204
|
|
| 160 |
.195
|
|
| 161 |
.195
|
|
| 162 |
.187
|
|
| 163 |
.186
|
|
| 164 |
.178
|
|
| 165 |
.167
|
|
| 166 |
.166
|
|
| 167 |
.161
|
|
| 168 |
.149
|
|
| 169 |
.140
|
|
| 170 |
.124
|
|
| 171 |
.115
|
|
| 172 |
.111
|
|
| 173 |
.096
|
|
| 174 |
.096
|
|
| 175 |
.053
|
|
| 176 |
.038
|
|
| 177 |
.032
|
|
| 178 |
.030
|
|
| 179 |
.029
|
|
| 180 |
.021
|
|
| 181 |
.015
|
|
| 182 |
.014
|
|
| 183 |
.011
|
|
| 184 |
.011
|
|
| 185 |
.003
|
|
| 186 |
.000
|
|
| 187 |
.000
|
|
| 188 |
.000
|
|
| 189 |
.000
|
|
| 190 |
.000
|
|
| 191 |
.000
|
|
| 192 |
.000
|
|
| 193 |
.000
|
|
| 194 |
.000
|
|
| 195 |
.000
|
|
| 196 |
.000
|
|
| 197 |
.000
|
|
| 198 |
.000
|
|
| 199 |
.000
|
|
| 200 |
.000
|
|
| 201 |
.000
|
|
| 202 |
.000
|
|
| 203 |
.000
|
|
| 204 |
.000
|
|
| 205 |
.000
|
|
| 206 |
.000
|
|
| 207 |
.000
|
|
| 208 |
.000
|
|
| 209 |
.000
|
|
| 210 |
.000
|
|
| 211 |
.000
|
|
| 212 |
.000
|
|
| 213 |
.000
|
|
| 214 |
.000
|
|
| 215 |
.000
|
|
| 216 |
.000
|
|
| 217 |
.000
|
|
| 218 |
.000
|
|
| 219 |
.000
|
|
| 220 |
.000
|
|
| 221 |
.000
|
|
| 222 |
|
|
| 223 |
|
|
| 224 |
|
|
| 225 |
|
|
| 226 |
|
|
| 227 |
|
|
| 228 |
|
|
| 229 |
|
|
| 230 |
|
|
| 231 |
|
|
| 232 |
|
|
| 233 |
|
|
| 234 |
|
|
| 235 |
|
|
| 236 |
|
|
| 237 |
|
|
| 238 |
|
|
| 239 |
|
|
| 240 |
|
|
| 241 |
|
|
| 242 |
|
|
| 243 |
|
|
| 244 |
|
|
| 245 |
|
|
| 246 |
|
|
| 247 |
|
|
| 248 |
|
|
| 249 |
|
|
| 250 |
|
|
| 251 |
|
|
| 252 |
|
|
| 253 |
|
|
| 254 |
|
|
| 255 |
|
|
| 256 |
|
|
| 257 |
|
|
| 258 |
|
|
| 259 |
|
|
| 260 |
|
|
| 261 |
|
|
| 262 |
|
|
| 263 |
|
|
| 264 |
|
|
| 265 |
|
|
| 266 |
|
|
| 267 |
|
|
| 268 |
|
|
| 269 |
|
|
| 270 |
|
|
| 271 |
|
|
| 272 |
|
|
| 273 |
|
|
| 274 |
|
|
| 275 |
|
|
| 276 |
|
|
| 277 |
|
|
| 278 |
|
|
| 279 |
|
|
| 280 |
|
|
| 281 |
|
|
| 282 |
|
|
| 283 |
|
|
| 284 |
|
|
| 285 |
|
|
| 286 |
|
|
| 287 |
|
|
| 288 |
|
|
| 289 |
|
|
| 290 |
|
|
| 291 |
|
|
| 292 |
|
|
| 293 |
|
|
| 294 |
|
|
| 295 |
|
|
| 296 |
|
|
| 297 |
|
|
| 298 |
|
|
| 299 |
|
|
| 300 |
|
|
| 301 |
|
|
| 302 |
|
|
| 303 |
|
|
| 304 |
|
|
| 305 |
|
|
| 306 |
|
|
| 307 |
|
|
| 308 |
|
|
| 309 |
|
|
| 310 |
|
|
| 311 |
|
|
| 312 |
|
|
| 313 |
|
|
| 314 |
|
|
| 315 |
|
|
| 316 |
|
|
| 317 |
|
|
| 318 |
|
|
| 319 |
|
|
| 320 |
|
|
| 321 |
|
|
| 322 |
|
|
| 323 |
|
|
| 324 |
|
Benchmark bibtex
@article{BAKER2022104913,
                title = {Deep learning models fail to capture the configural nature of human shape perception},
                journal = {iScience},
                volume = {25},
                number = {9},
                pages = {104913},
                year = {2022},
                issn = {2589-0042},
                doi = {https://doi.org/10.1016/j.isci.2022.104913},
                url = {https://www.sciencedirect.com/science/article/pii/S2589004222011853},
                author = {Nicholas Baker and James H. Elder},
                keywords = {Biological sciences, Neuroscience, Sensory neuroscience},
                abstract = {Summary
                A hallmark of human object perception is sensitivity to the holistic configuration of the local shape features of an object. Deep convolutional neural networks (DCNNs) are currently the dominant models for object recognition processing in the visual cortex, but do they capture this configural sensitivity? To answer this question, we employed a dataset of animal silhouettes and created a variant of this dataset that disrupts the configuration of each object while preserving local features. While human performance was impacted by this manipulation, DCNN performance was not, indicating insensitivity to object configuration. Modifications to training and architecture to make networks more brain-like did not lead to configural processing, and none of the networks were able to accurately predict trial-by-trial human object judgements. We speculate that to match human configural sensitivity, networks must be trained to solve a broader range of object tasks beyond category recognition.}
        }
Ceiling
0.94.Note that scores are relative to this ceiling.
Data: Baker2022fragmented
Metric: accuracy_delta